Doherty threshold
The tendency for a user's own pace to follow the machine's. A slow reply breaks the sequence of actions someone was holding in mind, so they slow down too — but the cost scales smoothly with delay.
Start with the number, because the number is wrong. Doherty and Thadhani's “The Economic Value of Rapid Response Time” (1982) is a customer-facing IBM brief, not the peer-reviewed article it is usually credited to, and it never mentions 400 milliseconds. It argues for “sub-second” response; its fastest reported data point is 0.3 seconds and its card-wiring tests bottom out at 0.25 seconds. The popular formulation, that productivity soars under 400 ms, was added later by people summarising it. So there is no line to pass or fail, and a response-time budget written against one is fiction.
The brief's own content is IBM field observations, and they are large. A programmer completed about 180 transactions per hour at three-second system response and 371 per hour at 0.3 seconds, a 106% increase. At the National Institutes of Health computer centre, as simultaneous users grew to almost 400 and average response degraded to four seconds, the time to complete an average task rose 50%, from 32 to 48 minutes, costing an estimated 22,500 extra terminal hours and $900,000 a month. None of it had a control group, and the organisation publishing it sold processor upgrades. The mechanism Doherty and Kelisky proposed in 1979 is quoted in the brief: people “seem to have a sequence of actions in mind, contained in a short-term mental memory buffer”, and delay “seem[s] to disrupt the thought processes”. That is an argument for protecting a user mid-sequence, not for a uniform speed target across a product.
Shneiderman audited this literature in 1984 and the audit is more useful than the brief. He confirms the interaction-rate findings — a circuit designer in Smith's 1983 study went from 800 interactions per hour at 1.5 seconds to 4,300 at 0.4 seconds — then says the quiet part: “these results are strong, but they only measure interactions per hour, not productivity.” Part of the gain is that users simply pick up the pace of the system; Boies found user think time rising from about 15 to 24 seconds as response went from 1 to 10 seconds. One study's faster group also each had their own terminal while controls shared one between 1.8 people. And the effect is not universal: Dannenbring found that moving response time from 0 to 5 to 10 seconds changed neither performance time nor satisfaction for novice or experienced programmers debugging a short BASIC program. Counting actions per hour will flatter a speed-up that produced no extra work.
Speed also buys errors. Barber and Lucas studied 100 professional circuit-layout clerks and found a U-shaped error curve: 49 errors out of 287 transactions at a four-second response, 16 out of 222 at twelve seconds, and 70 out of 151 at twenty-four seconds. The lowest error rate was at twelve seconds — faster responses produced hasty decisions, slower ones burdened short-term memory. Productive transactions, total minus errors, still rose almost linearly as response fell, so faster was still better overall, but Shneiderman concludes there is “little evidence to support the claim that fewer errors are made with very short response times (under 1 second).” On an irreversible path, a faster interface mostly produces faster mistakes.
The modern evidence is where this principle earns its place, and it prices latency rather than thresholding it. Brutlag injected server-side delay into Google web search: a 50 ms pre-header delay produced no measurable change in daily searches per user, 100 ms produced −0.20%, a 200 ms post-header delay −0.29%, and 400 ms −0.59% over six weeks. The damage grew with exposure — the 400 ms group was down 0.44% in the first three weeks and 0.74% in the second three — and persisted at −0.21% across the five weeks after the delay was removed. At Bing, Kohavi and colleagues slowed 10% of users by 100 ms and another 10% by 250 ms and concluded that every 100 ms of speedup improves revenue by 0.6%, with a linear approximation holding across slowdown magnitudes. Neither dataset has a knee at 400 ms, so the useful artefact is your own slope per 100 ms, not a target to clear.
The same Bing work shows where latency is free: delaying the right-pane elements of the results page by 250 ms had no detectable impact on key metrics across almost 20 million users. What costs money is delay in front of the thing the user came for — which is also why window.onload is a poor proxy. The authors note an Amazon page rendering above the fold in 2.0 seconds while onload fires at 5.2, and Gmail firing onload at 3.3 seconds when only the progress bar is visible.
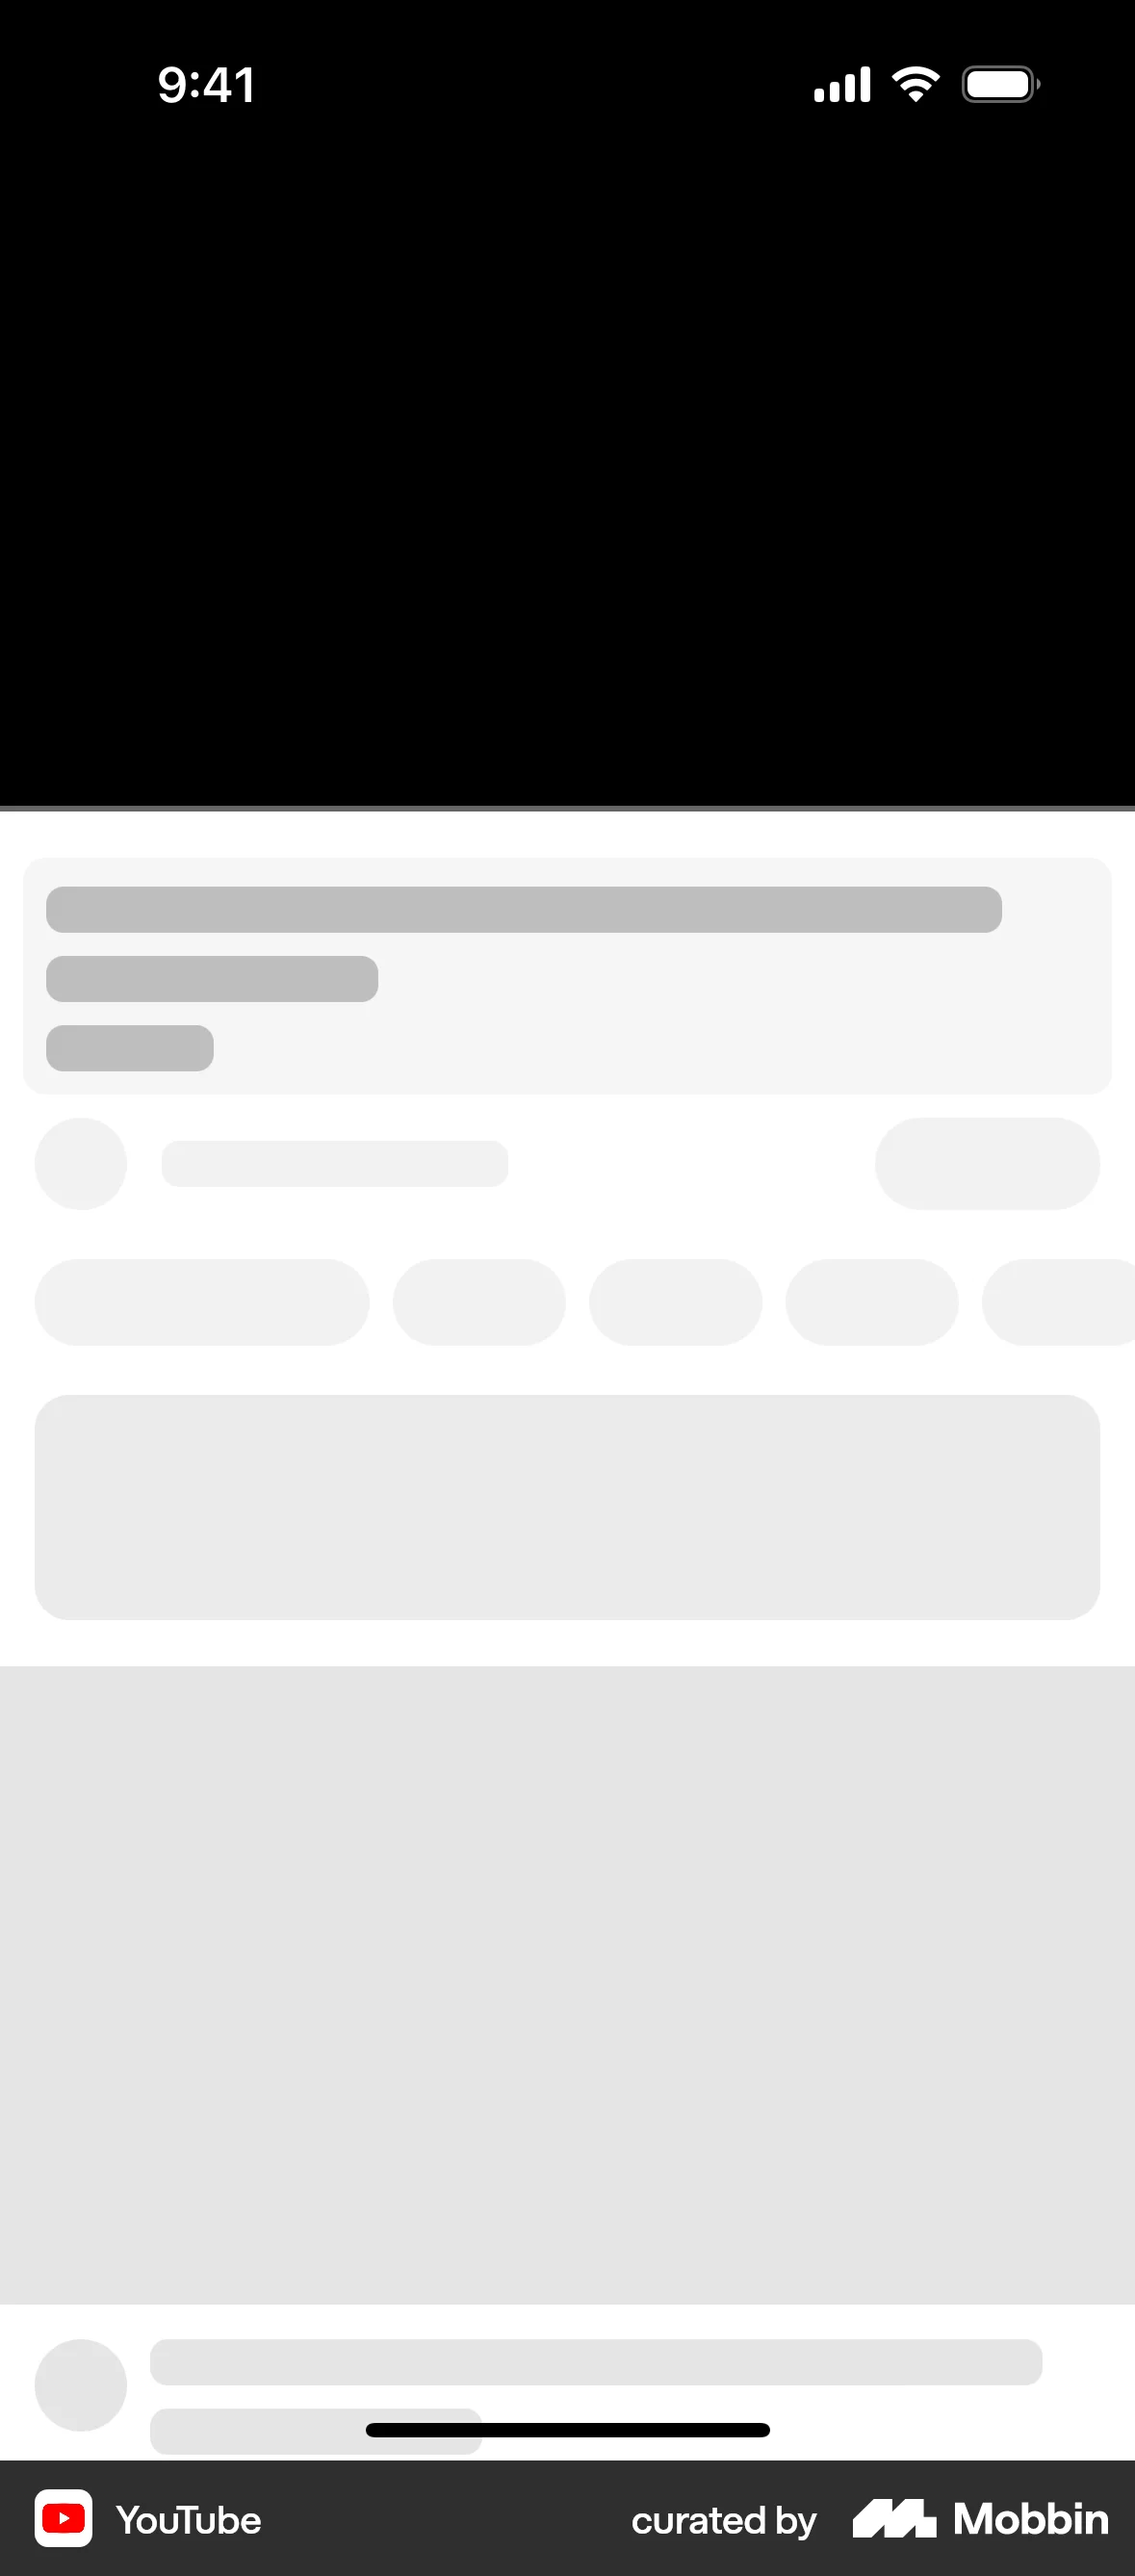
The two patterns usually prescribed for this principle have almost no evidence behind them. The best public test of skeleton screens is Viget's: 136 participants saw loading animations of identical length, and the skeleton did worst on every measure, with a mean perceived wait of 2.82 seconds against 2.41 for a spinner and 2.29 for a blank screen. No significance tests were reported, the samples are small and the stimuli were simulated GIFs, so this does not show that skeletons hurt; it shows that nobody has shown they help. Optimistic UI has no published controlled evidence at all. Grade the two halves separately: that responsiveness pays, roughly in proportion to milliseconds, rests on large field experiments; the 400 ms threshold and the widgets sold with it do not.
When it holds
- Interaction-bound, repetitive work. The large historical gains came from people issuing hundreds of commands an hour — 180 to 371 per hour for programmers, 800 to 4,300 for a skilled circuit designer. A flow with three taps has little pace to pick up.
- When the delay sits in front of the primary content. A 250 ms delay on Bing's right pane was undetectable across almost 20 million users, while 100 ms added to the whole page was worth 0.6% of revenue per user.
- Over weeks, not sessions. Google's 400 ms delay cost 0.44% of daily searches per user in the first three weeks and 0.74% in the next three, and still cost 0.21% for five weeks after the delay was removed.
- Smoothly, with no cliff. Bing confirmed that a linear approximation held across slowdown magnitudes, and Google measured nothing at 50 ms but −0.20% at 100 ms. There is no special status to 400 ms.
- Largely absent for novices on deliberative tasks. Varying response time from 0 to 5 to 10 seconds changed neither performance time nor satisfaction for novice or experienced programmers debugging a short program.
- Reverses where mistakes are costly. Barber and Lucas found the lowest error rate at a twelve-second response; at four seconds their clerks made 49 errors in 287 transactions because they decided hastily.
- Predictability counts alongside the mean. Shneiderman recommends that variations below one quarter or above twice the mean response time carry an informative message, or that fast responses be slowed so the pace stays stable.
How to apply
- Give the control the user touched a state change within about a tenth of a second — pressed, disabled, or an inline spinner in the button. Google could measure nothing from a 50 ms delay and −0.20% from 100 ms, which is roughly the budget for “nothing has happened yet”.
- Render the thing the user came for first and let sidebars, recommendation rails, counters and badges arrive late. That secondary region is where Bing hid 250 ms from 20 million users.
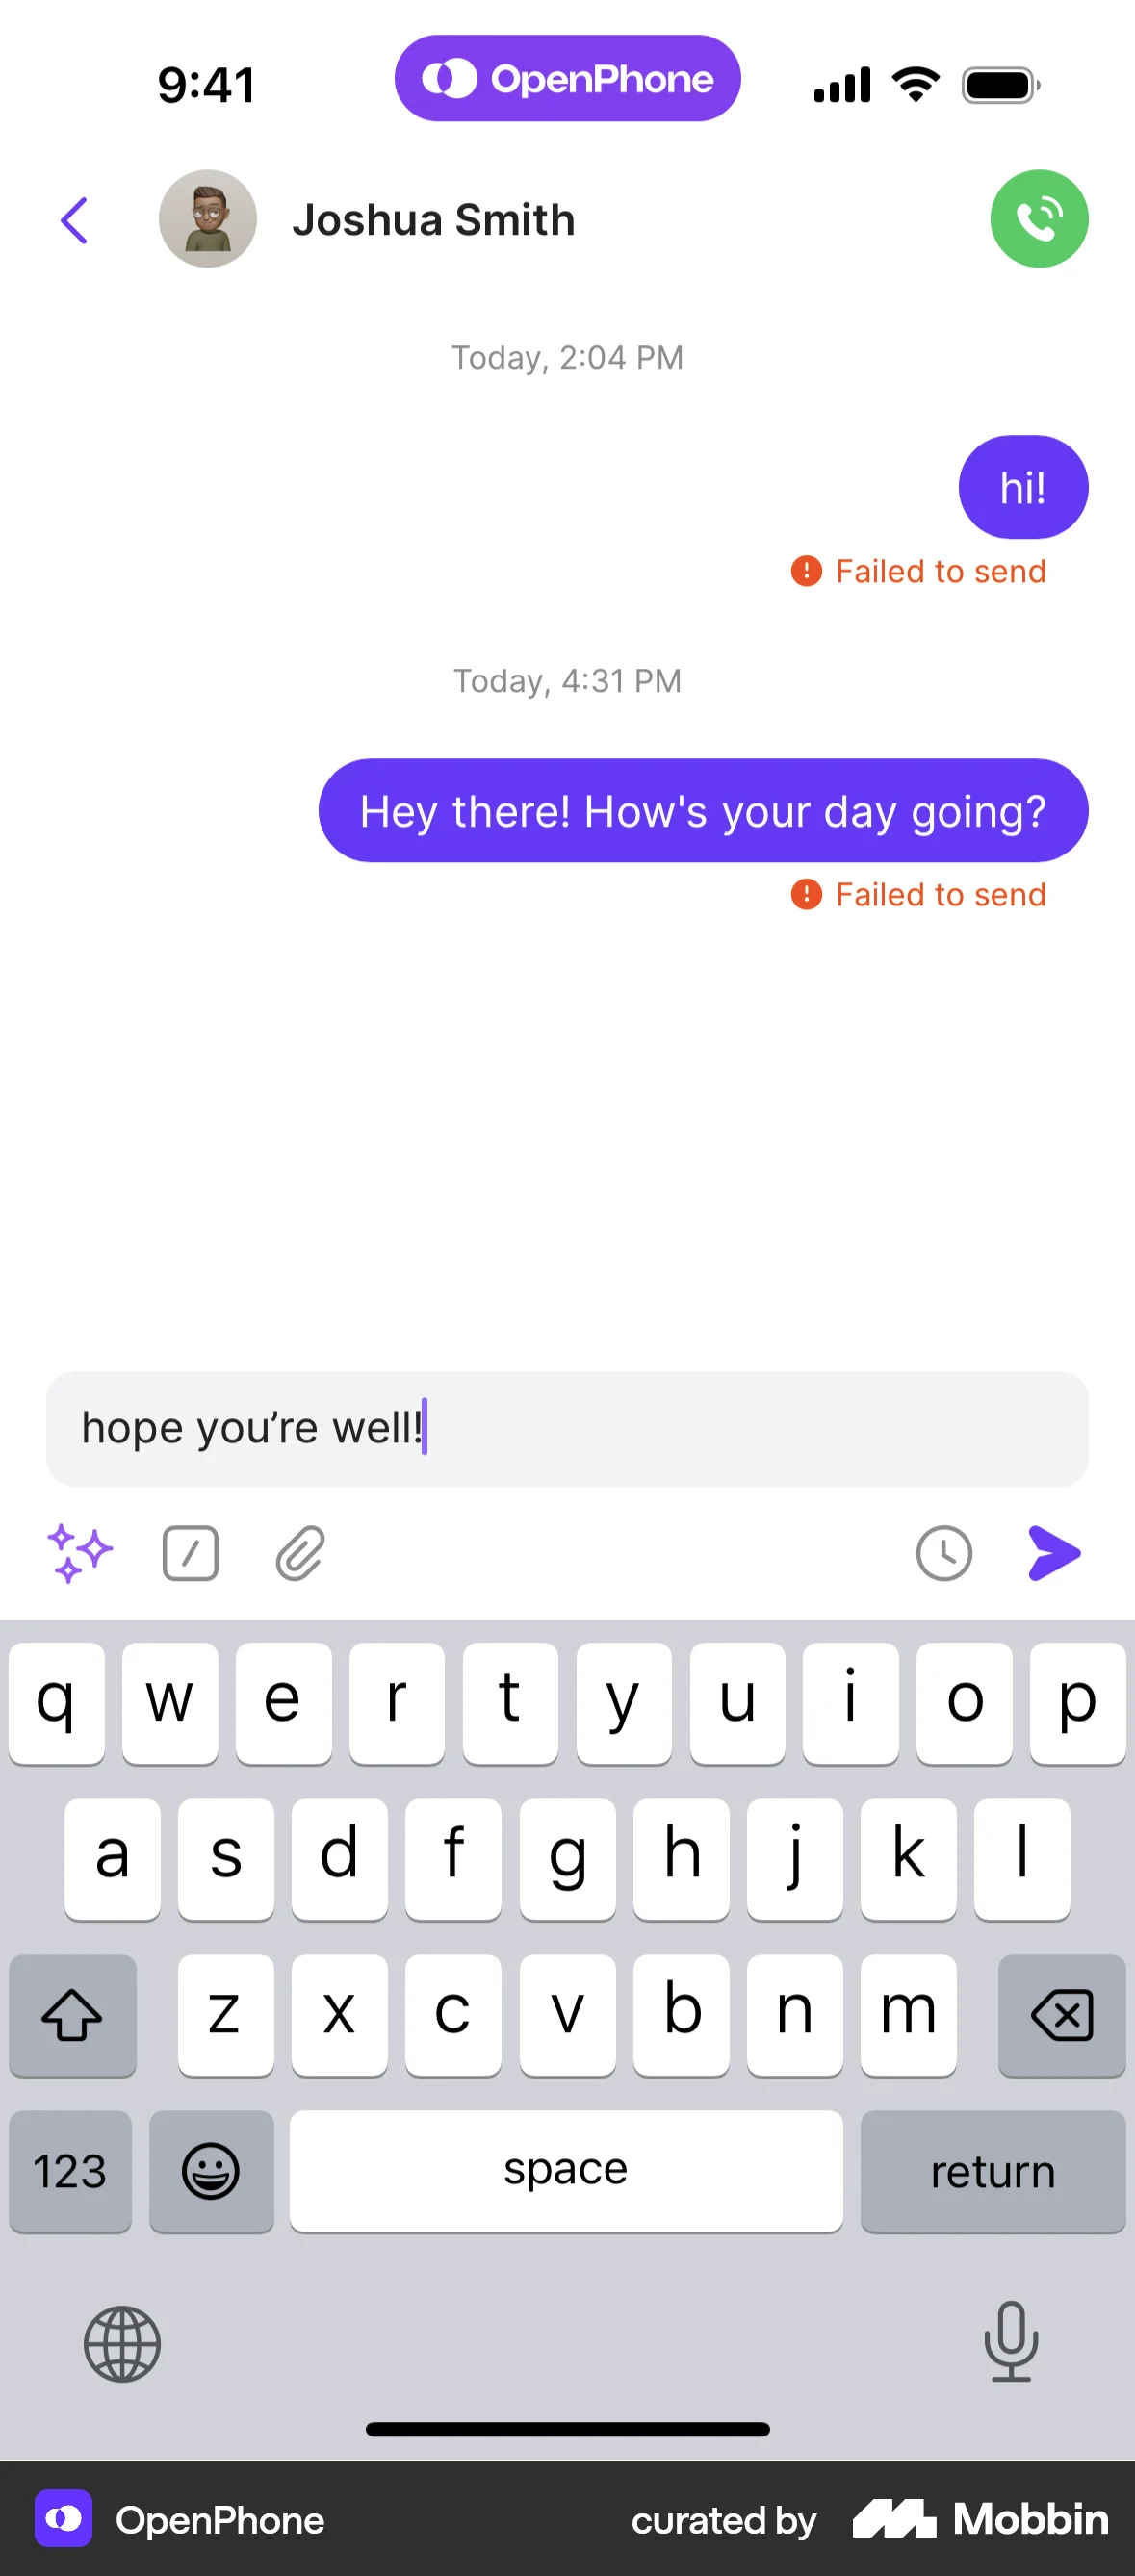
- Write the result into the UI on the gesture for near-certain, cheap-to-reverse actions: liking, checking off, reordering a list, adding to a cart. Reconcile when the response lands.
- Build the failure path with the optimistic one: revert the single item in place, keep whatever the user typed, and put retry on the row that failed rather than in a modal that discards the input.
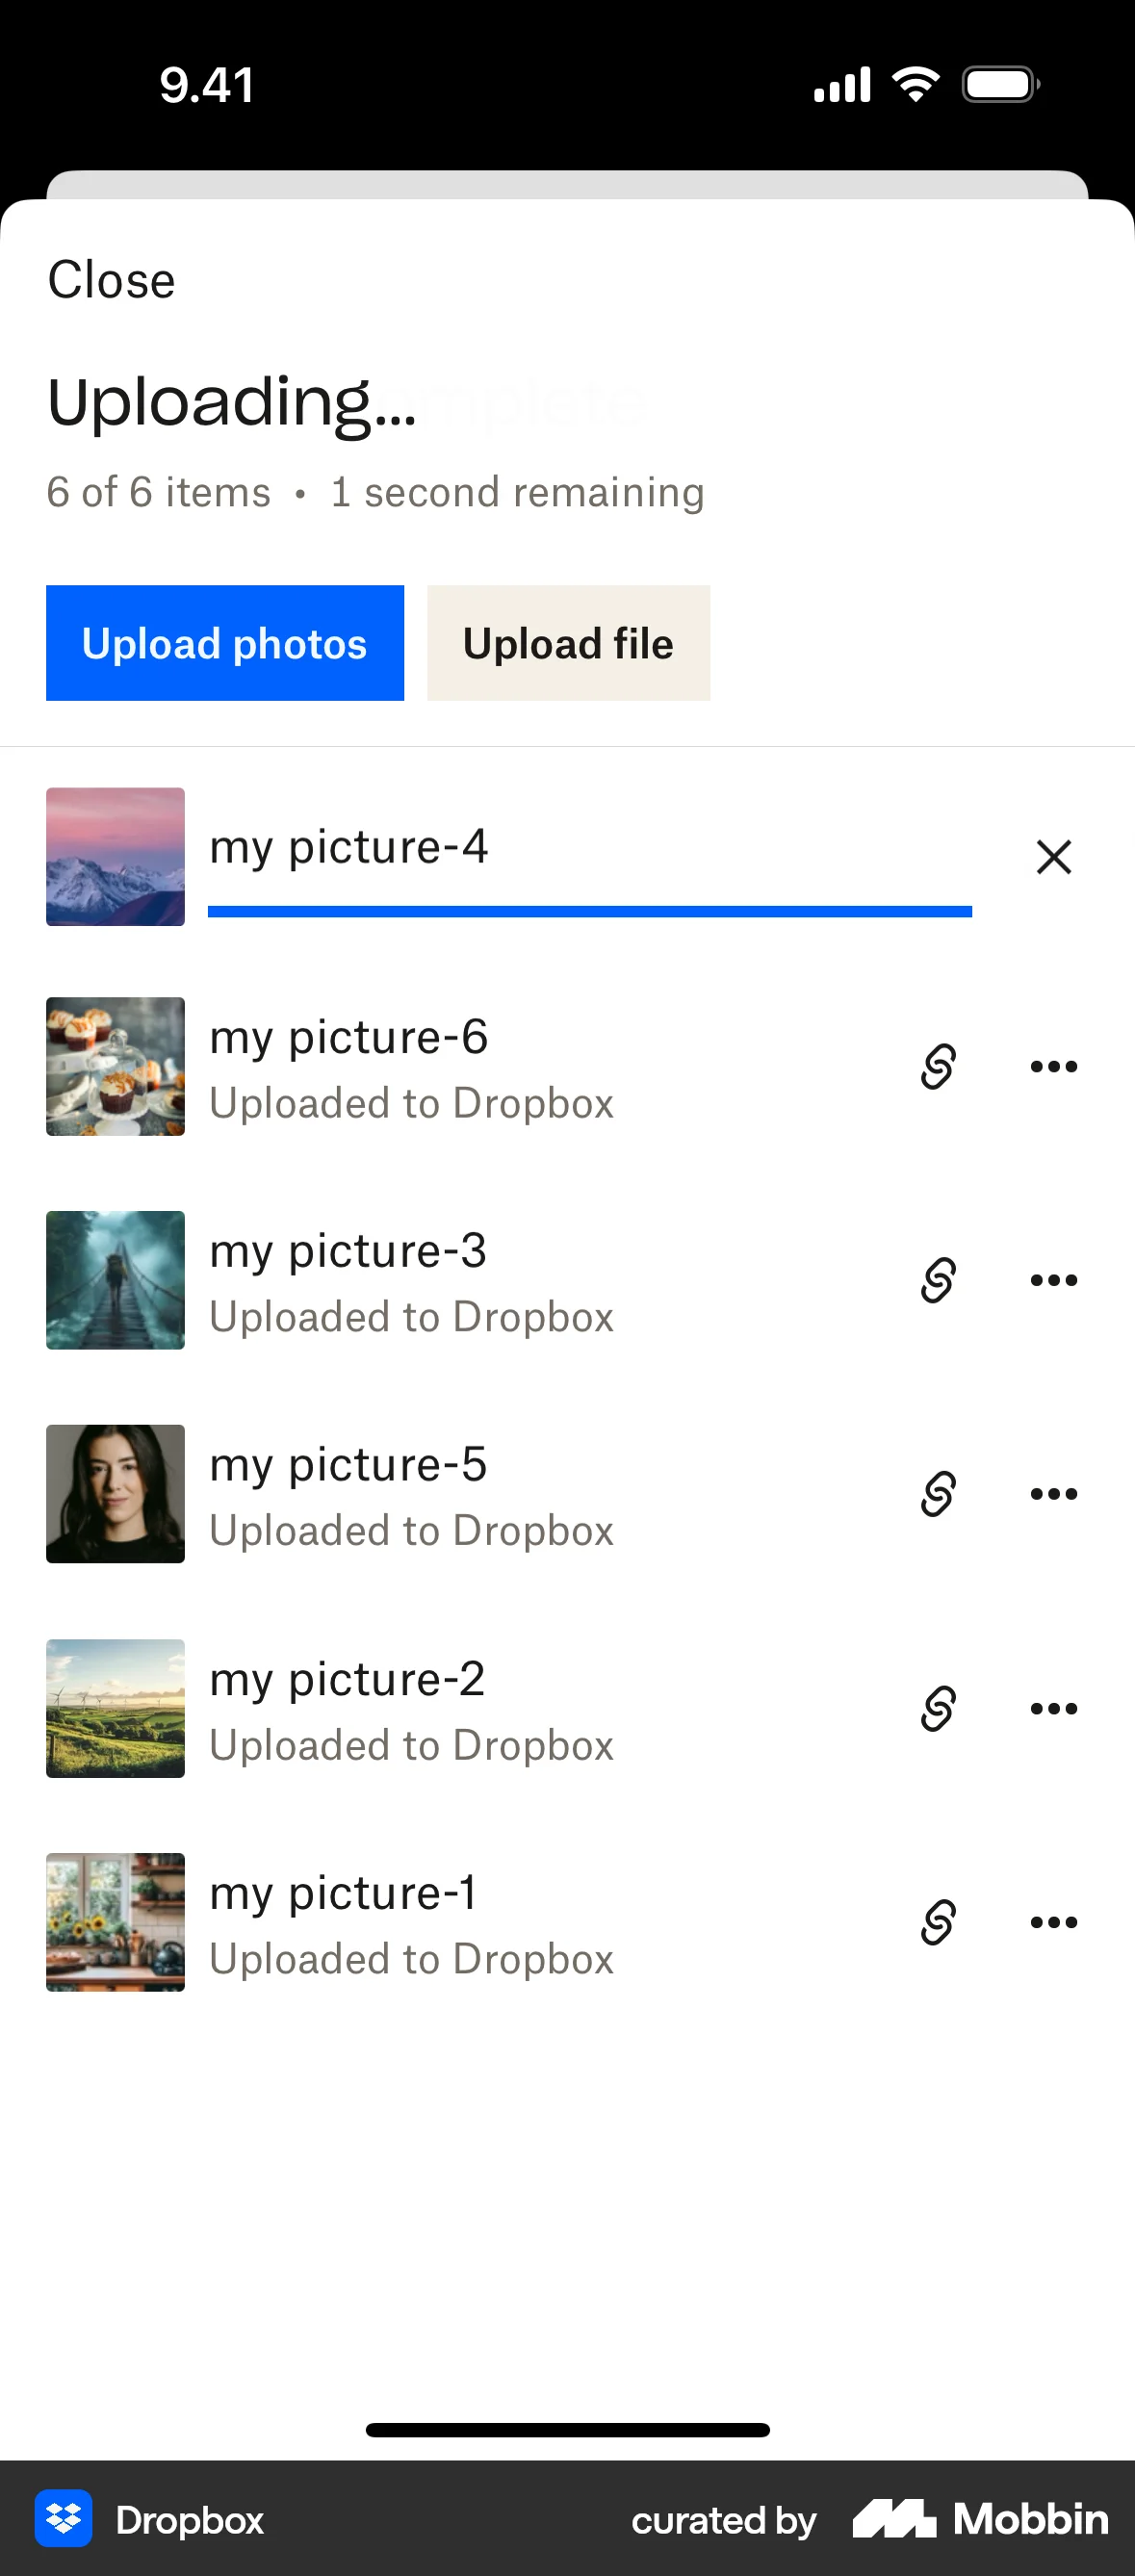
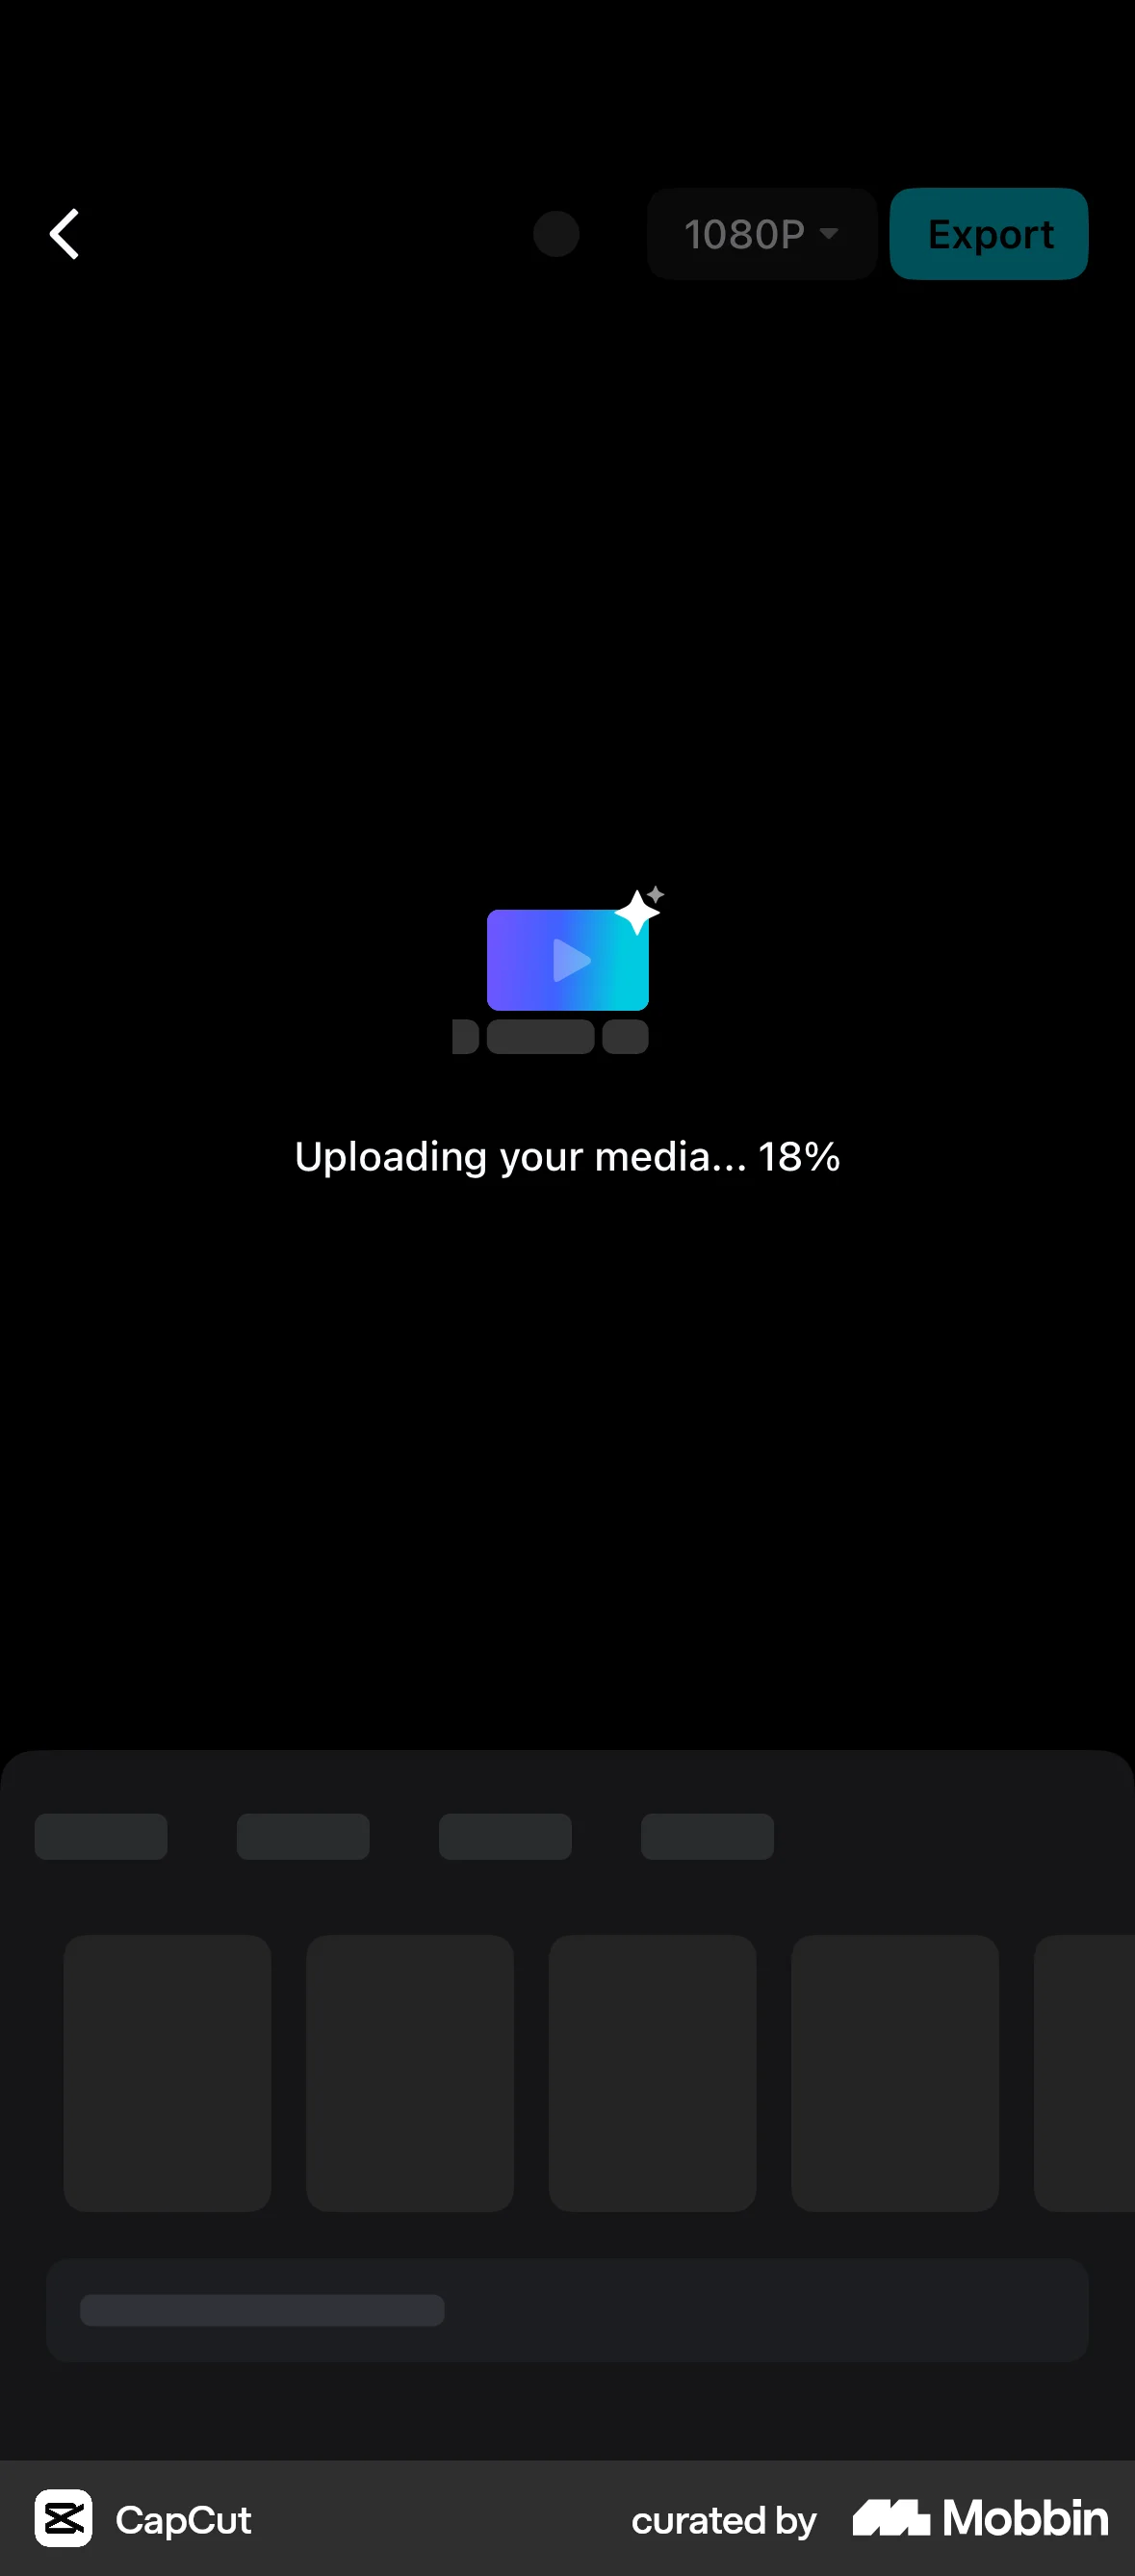
- Reserve the exact space the content will occupy so nothing jumps when it arrives, and treat layout stability as the reason for a skeleton. The one public test found perceived waits longer with skeletons than with a spinner.
- For work that genuinely takes seconds, label the step in progress rather than showing a skeleton. A skeleton promises imminent layout, which a slow pipeline cannot keep.
- Put an explicit message on the slow path when the same action returns in 80 ms sometimes and 3 seconds other times, so the pace stays legible instead of only the average looking good.
What to avoid
- Treating 400 ms as a pass/fail line. It is not in Doherty and Thadhani, and neither the Google nor the Bing data shows a knee there — a 500 ms response is not a failure and a 390 ms one is not a win.
- Faking speed. A success state for an operation the server has not accepted, or a spinner still spinning after the request failed, is the anti-pattern here: the ethical line is that optimism has to reconcile with errors, visibly and in the same place the optimistic result appeared.
- Optimistic updates on actions that are expensive or hard to reverse — payments, sends, publishes, destructive deletes. Confirm those from the server before the interface says they happened.
- Judging speed by window.onload. An Amazon page can render above the fold in 2.0 seconds with onload at 5.2; Gmail's onload fires at 3.3 seconds when only the progress bar is visible. Measure time to the content that matters.
- Accelerating a flow where errors are expensive and hard to detect. Barber and Lucas's clerks were least accurate at the fastest response times.
- Status that exists only as pixels. WCAG 2.2 Success Criterion 4.1.3, Status Messages (Level AA), requires busy, progress and success messages to be programmatically determinable — via role="status" and equivalents — so assistive technology announces them without moving focus. An optimistic row that appears silently fails it.
Real-world examples
Measuring it
- Primary: your own slope, from a slowdown experiment rather than an estimate. Add a fixed delay to a random slice of traffic (Bing used 100 ms and 250 ms to 10% of users each, for two weeks) and read the change in your key metric per 100 ms.
- Measure it per user over weeks, not per session. The Google delay cost nearly twice as much in the second half of six weeks as in the first, and part of the loss survived the fix.
- Secondary: time to the primary content — first meaningful result, above-the-fold paint, time to first row — at p75 and p95, not as a mean page load time.
- Backfire metric: error, undo and duplicate-submission rates on the accelerated path. Rising corrections mean you bought interactions per hour and paid in mistakes, which is the Barber and Lucas pattern.
- Backfire metric for optimistic UI: the share of optimistic actions later reverted, the share of those users who retried, and support contacts about items that appeared and then vanished. A high revert rate with a low retry rate means the interface confirmed things that never happened.
References
- Doherty & Thadhani (1982). The Economic Value of Rapid Response Time. IBM Form GE20-0752-00.
- Shneiderman (1984). Response Time and Display Rate in Human Performance with Computers. ACM Computing Surveys 16(3), 265–285.
- Barber & Lucas (1983). System Response Time, Operator Productivity, and Job Satisfaction. Communications of the ACM 26(11), 972–986.
- Brutlag (2009). Speed Matters for Google Web Search. Google, Inc.
- Kohavi, Deng, Longbotham & Xu (2014). Seven Rules of Thumb for Web Site Experimenters. KDD '14, 1857–1866.
- Faulkner & Olvera (2017). A Bone to Pick with Skeleton Screens. Viget.
- W3C. WCAG 2.2 Success Criterion 4.1.3 Status Messages (Level AA).
For agents
An agent-friendly guide to this principle lives at /agents/doherty-threshold.md.
Our MCP server and skills for all principles are coming soon.
Similar principles
Disclaimer: The theories here are just that — theories. They may not apply universally and should be considered in context. Use your own judgment and consult additional sources when applying these principles.