Availability heuristic
The availability heuristic answers a frequency question by sampling memory instead of a base rate. Two inputs drive it — the number of instances retrieved and the felt difficulty of retrieving them — and they push in opposite directions.
The strand of this literature with the best record is availability-by-recall: judging a risk by counting the cases you have actually encountered. Hertwig, Pachur and Kurzenhäuser tested four candidate mechanisms against people's choices in three risk environments, and availability-by-recall and a regressed-frequency model conformed best. Pachur, Hertwig and Steinmann pitted availability against the affect heuristic across judged frequency, value of a statistical life and perceived risk: availability-by-recall, defined as occurrences of the risk in the respondent's own social network, fitted best overall, and encounters with risks in the media played a negligible role. Efendić's experiment supplies the causal version — asking participants to think of more deaths in their own social network raised both mortality judgments and the value placed on a single life, irrespective of affect, media coverage of the risk, or retrieval time. The availability doing the work is counted lived instances, not exposure on a screen, and a screen is the only channel an interface has.
The famous demonstrations are weaker than their reputation. Lichtenstein, Slovic, Fischhoff, Layman and Combs found a biased subjective frequency scale for causes of death — small frequencies overestimated, large ones underestimated, specific causes exaggerated or discounted — which participants could not correct when instructed to try. But that first pattern is exactly what a regressed-frequency model predicts with no appeal to memory, and in Hertwig and colleagues' comparison the two mechanisms performed at a nearly indistinguishable level. Sedlmeier, Hertwig and Gigerenzer challenged the letter-frequency task head on: across three studies, judgments of whether a letter is more common in first or second position generally followed the actual proportions, with low values overestimated and high ones underestimated. You cannot assume a user's frequency estimate is memory-distorted just because it came from memory.
The second mechanism is the one that inverts the obvious advice. Schwarz, Bless, Strack, Klumpp, Rittenauer-Schatka and Simons had people recall either six or twelve of their own assertive behaviours and then rate their assertiveness; those who produced twelve rated themselves less assertive, because twelve was hard to come up with and the difficulty itself was read as evidence. Weingarten and Hutchinson meta-analysed the paradigm across 142 papers, 263 studies and 582 effect sizes: the standard few-versus-many manipulation shows a medium-sized average effect, between about a third and a half of it mediated by subjective ease, with publication bias that reduces the standard effect by up to a third. Manipulations departing from that standard design produce smaller and often reversed effects, less strongly mediated by ease, so the direction of a retrieval-difficulty manipulation in a new flow is not predictable from the literature.
Both of the big clean tests come up empty. Yeager, Krosnick, Visser, Holbrook and Tahk ran seven highly cited social-psychological phenomena on randomly sampled, representative US adults; six replicated, more weakly than the meta-analytic estimates from student samples, and the one that did not was the ease-of-retrieval cross-over interaction. Groncki, Beaudry and Sauer found no ease-of-retrieval effect on eyewitness confidence or related judgments across three studies, then failed to replicate Schwarz et al.'s original result directly (N = 661), with both frequentist and Bayesian tests showing no evidence of an effect. Note what did work in three of their four studies: the manipulation moved perceived task difficulty as intended, and the judgment still did not move. A difficulty manipulation that demonstrably lands is not sufficient to move the number a user reports.
The one applied field result points the same way as Schwarz, not as the folk version. Fox asked business students mid-course to list either 2 or 10 ways the course could be improved. The ten-slot group rated the course higher — 5.52 against 4.92 on a 1–7 scale — while producing no more criticisms (2.1 against 1.6). What predicted the rating was the ratio of criticisms produced to criticisms solicited, not the count. Asking for more examples of a problem made the problem look smaller, which makes the cap you put on a feedback prompt a design decision with a measured sign.
There is, as far as this review found, no controlled evidence that making examples easy to recall works as a product intervention: no experiment tests whether a case-study shelf, a customer-story carousel or a “people like you” module changes a user's estimate of anything. The nearest controlled work shows the mechanism operating against accuracy. Fagerlin, Wang and Ubel had people choose between bypass surgery and angioplasty from cure rates given in prose plus patient anecdotes: 41% chose bypass when the anecdotes were representative of the cure rates and 20% when they were not. Reinforcing the same statistics with a pictograph and a quiz removed the anecdotes' influence (38% against 44%); the quiz alone did nothing (27% against 28%) and the pictograph alone was what worked. Tversky and Koehler's support theory covers the reading side — unpacking a category into explicitly named components raises its judged probability — so a list of named failure modes beside an offer is itself a probability manipulation. Build exemplars as a device that moves estimates in a direction you have not measured, and keep a graphical base rate on the same screen.
When it holds
- It holds best when the instances come from personal experience. Availability-by-recall over occurrences in the respondent's own social network fitted risk judgments better than affect-based models.
- It is weak for instances encountered through media. In the study that separated channels, media encounters played a negligible role — and media-style exposure is what an interface delivers.
- The direction depends on which input dominates. Retrieving more instances raises a frequency judgment; being asked for more than you can comfortably retrieve lowers the judgment those instances support.
- It reverses when the ask outruns supply. Students given ten slots for course criticisms rated the course higher than students given two, and the produced-to-solicited ratio, not the number produced, predicted the rating.
- Ease-of-retrieval effects are fragile outside the exact paradigm. Across 263 studies, manipulations departing from the standard few-versus-many design gave smaller and often reversed effects, less strongly mediated by ease.
- A working difficulty manipulation does not guarantee a judgment effect. In three of four studies the manipulation shifted perceived task difficulty as intended while the ratings did not move.
- It is weaker in the general population than in student labs. Of seven classic effects tested on representative US adults, six replicated but more weakly, and the ease-of-retrieval interaction was the one that did not appear.
- Frequency judgments are better calibrated than the folk version implies. Letter-position judgments generally tracked the actual proportions, with low values overestimated and high values underestimated — a regression pattern, not a memory bias.
How to apply
- Cap any “list your reasons” or “tell us why” prompt at two or three slots and never render an empty one. Ten slots a user can only half-fill made the thing being rated look better, and an unfilled list is a visible shortage read as evidence.
- Show the examples rather than asking the user to generate any. Reading named instances and producing them are different operations with opposite signs.
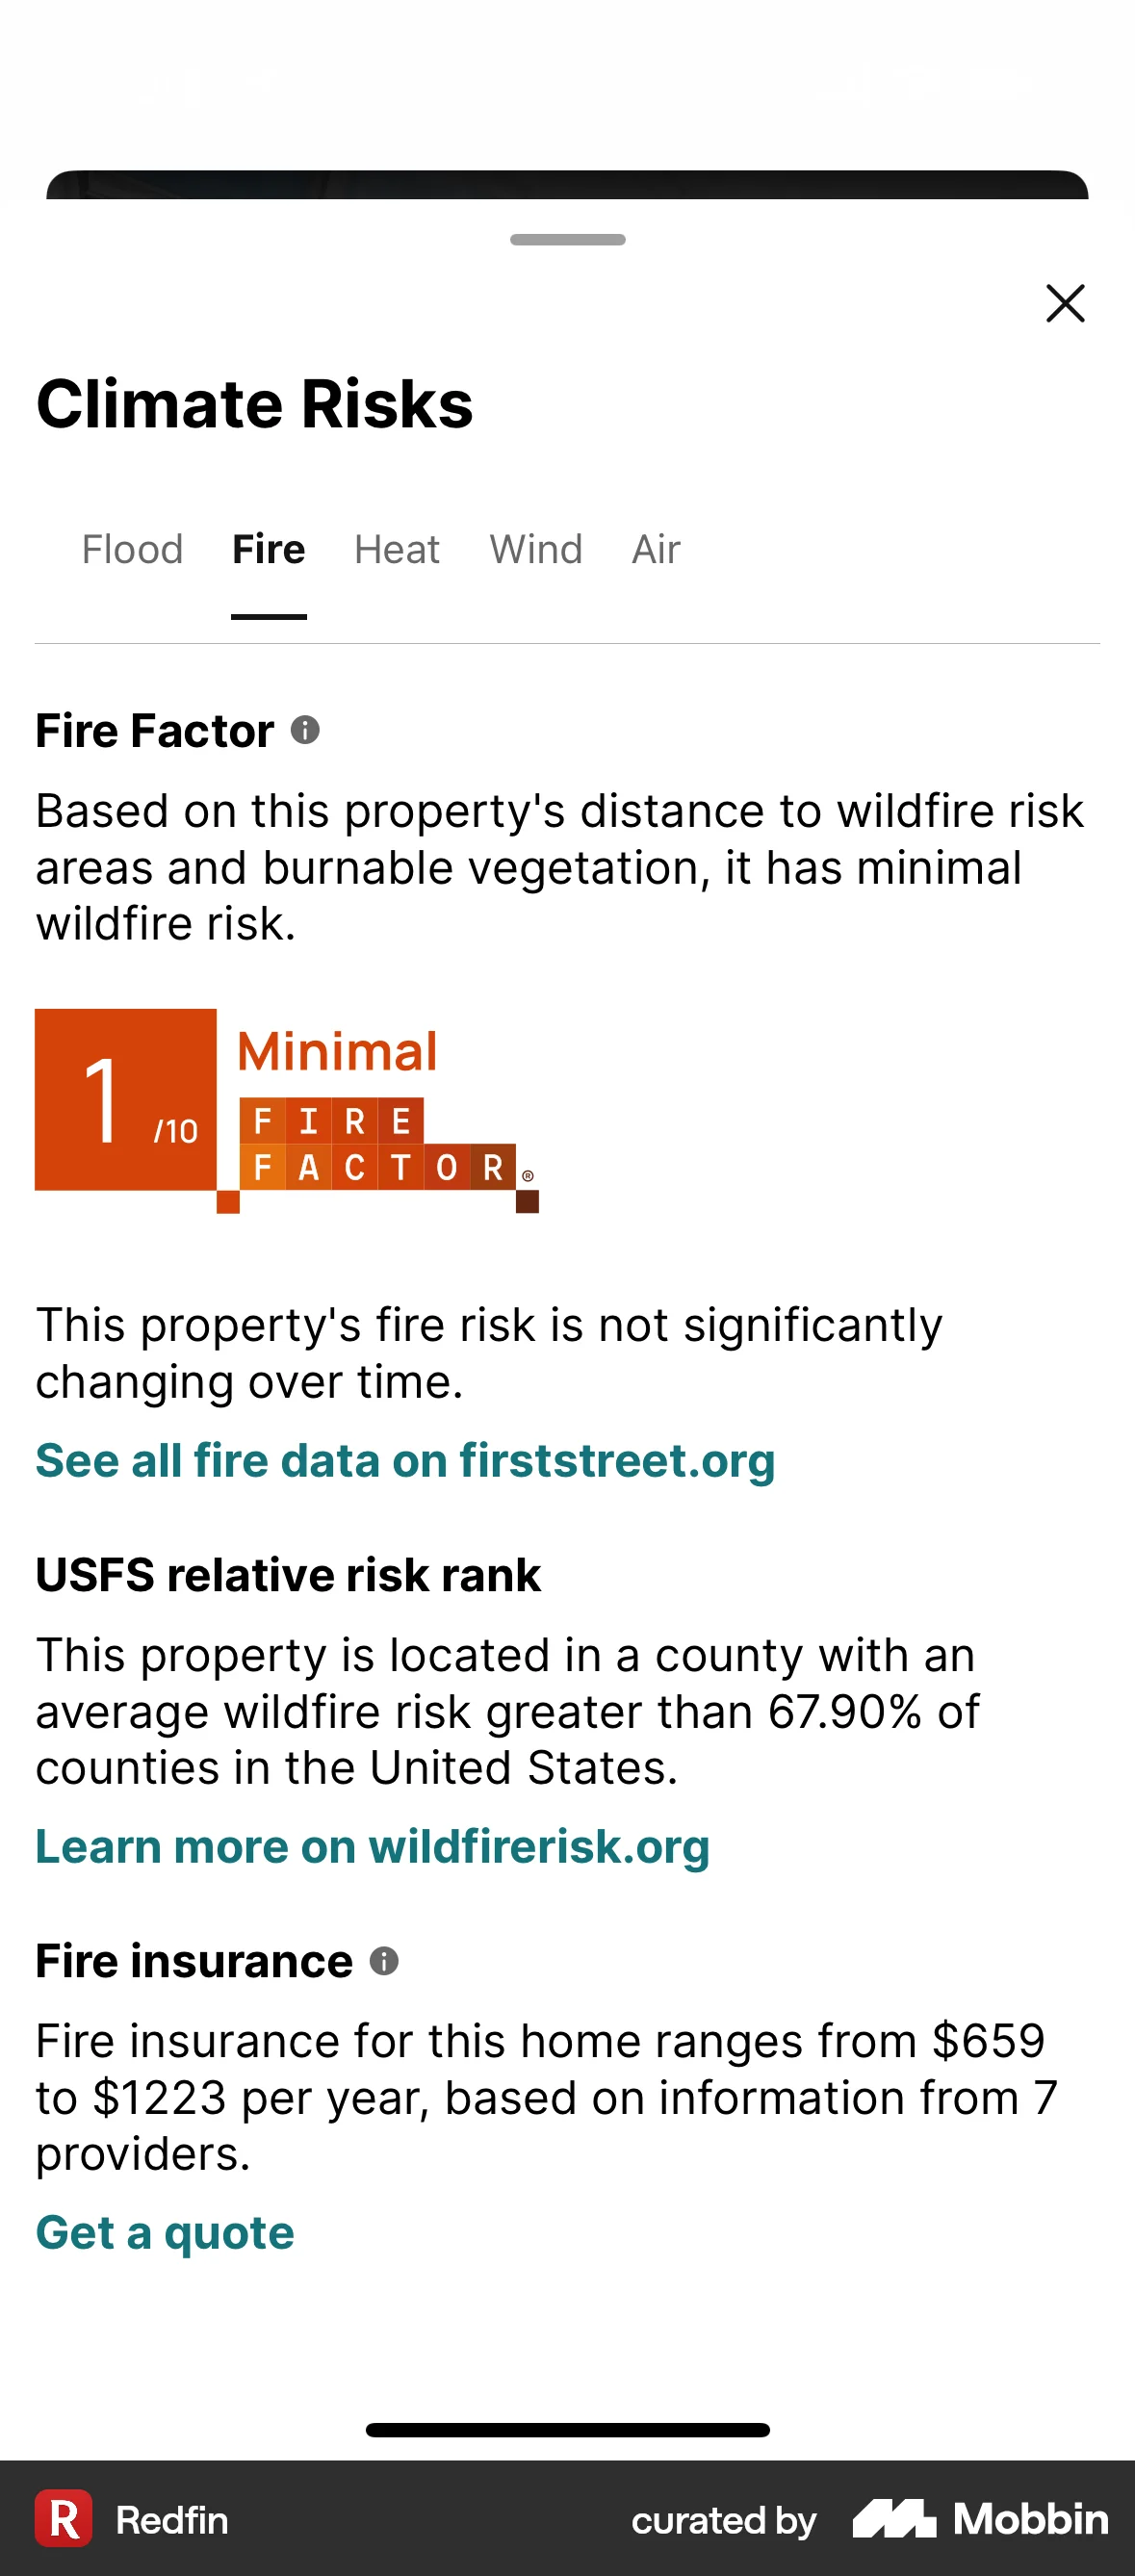
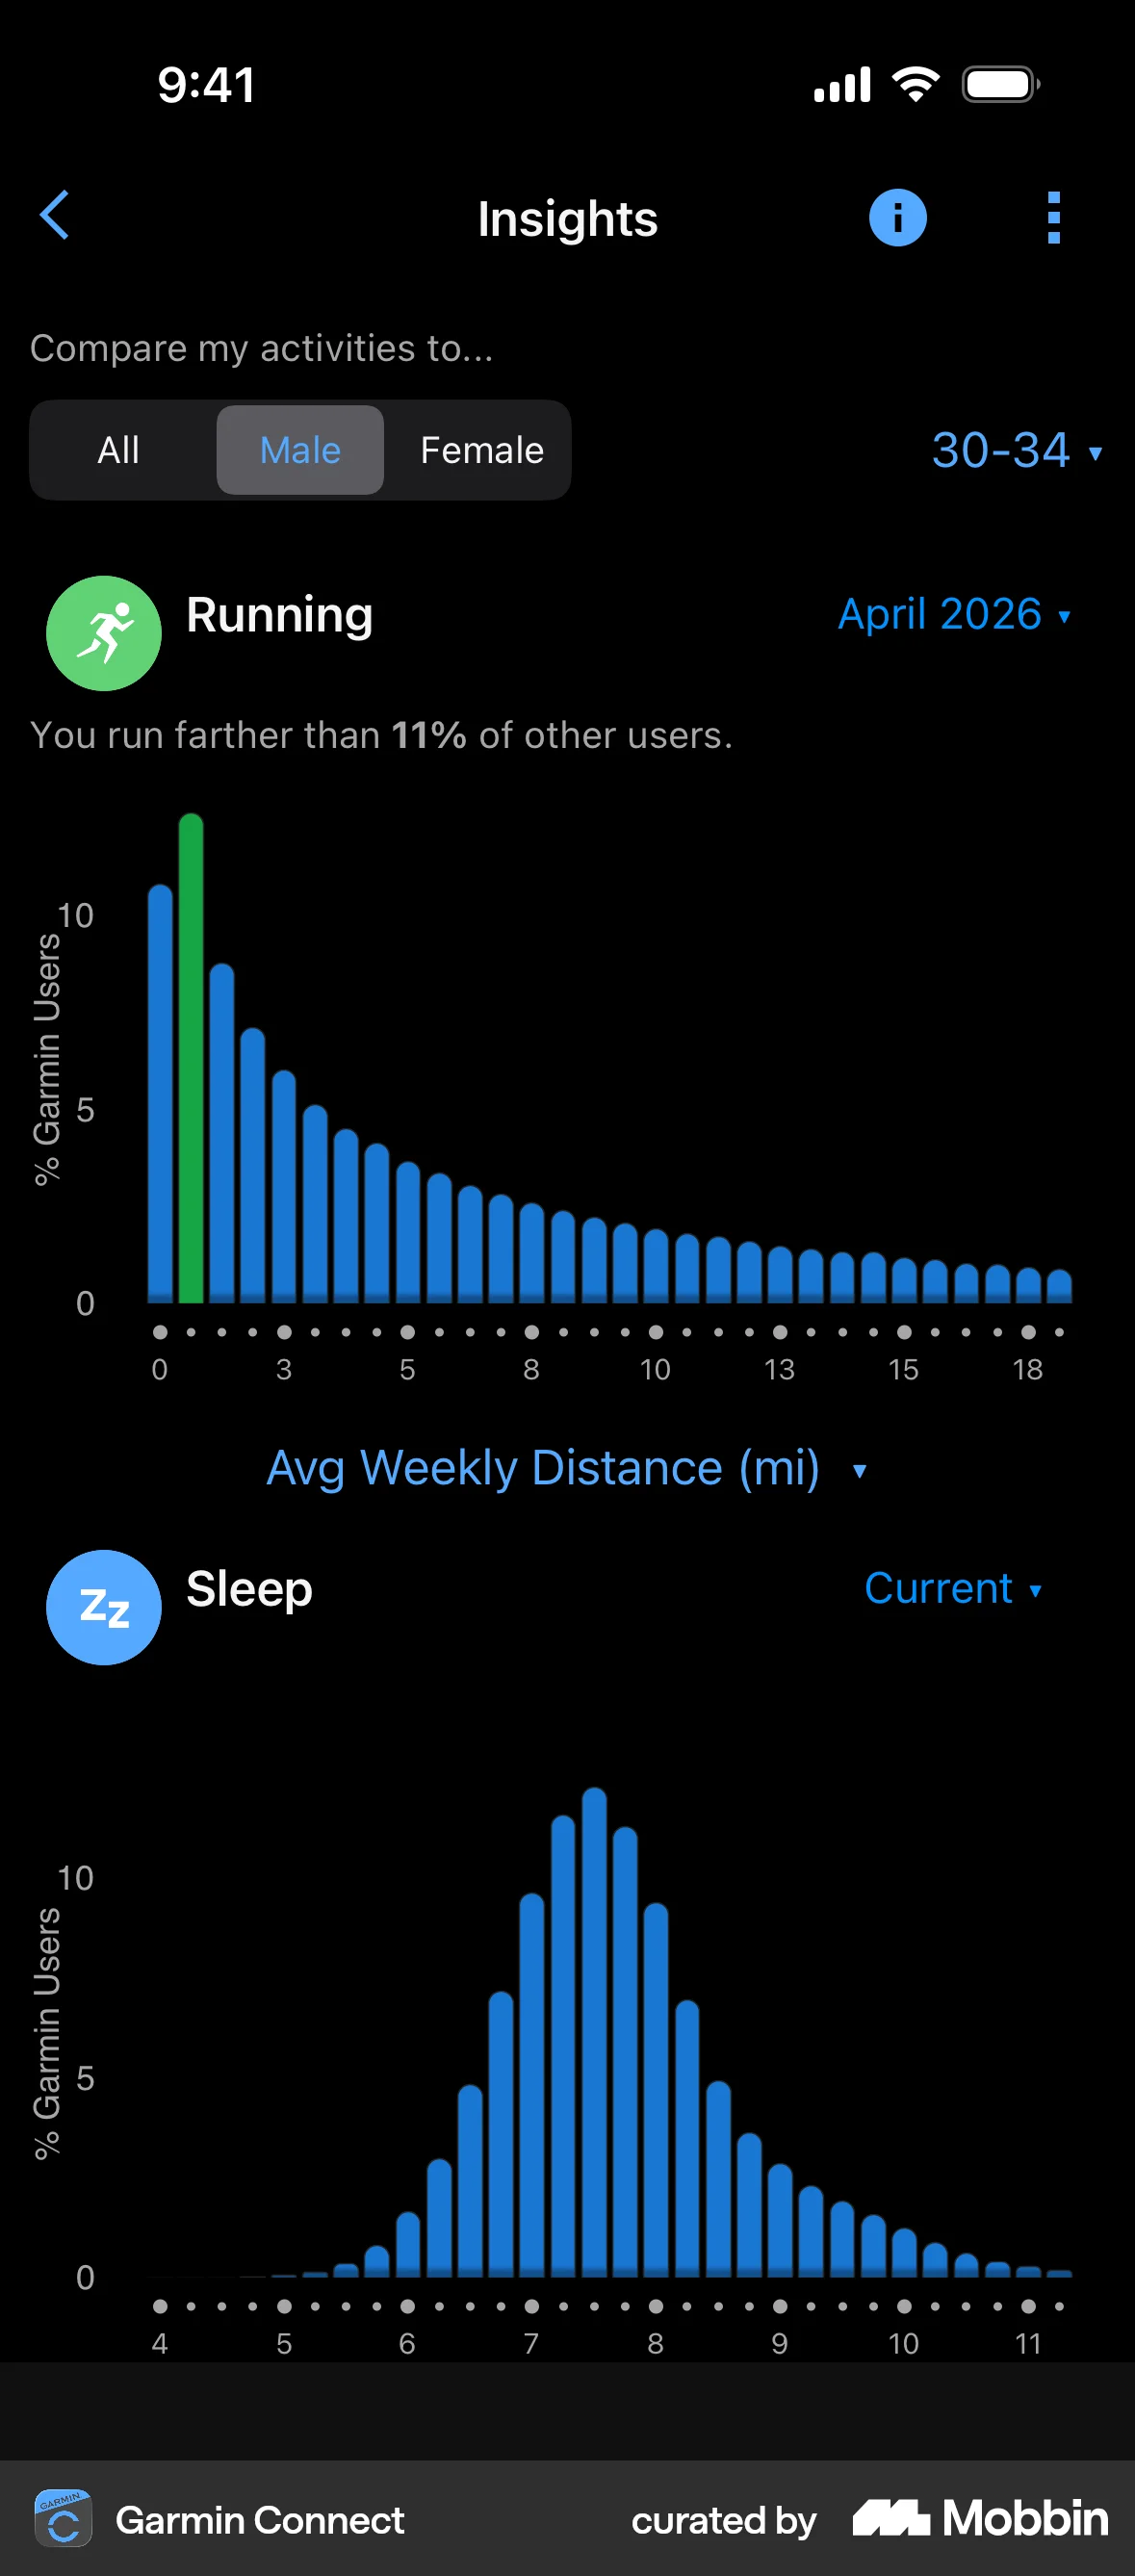
- Put a pictograph or icon array beside every frequency or risk claim, at the same prominence as the story. The graphical base rate was what removed anecdotes' pull on treatment choice; a comprehension quiz alone did nothing.
- Pick case studies from the segment the reader is in rather than your best logos. The availability that predicts judgment is occurrences in people's own circle, so a near-identical company does work an aspirational one does not.
- Keep the count of case studies and testimonials proportionate to your real outcome rate. Five successes on a page where one in five customers succeeds is a prevalence claim, and the exemplars will dominate the number printed next to them.
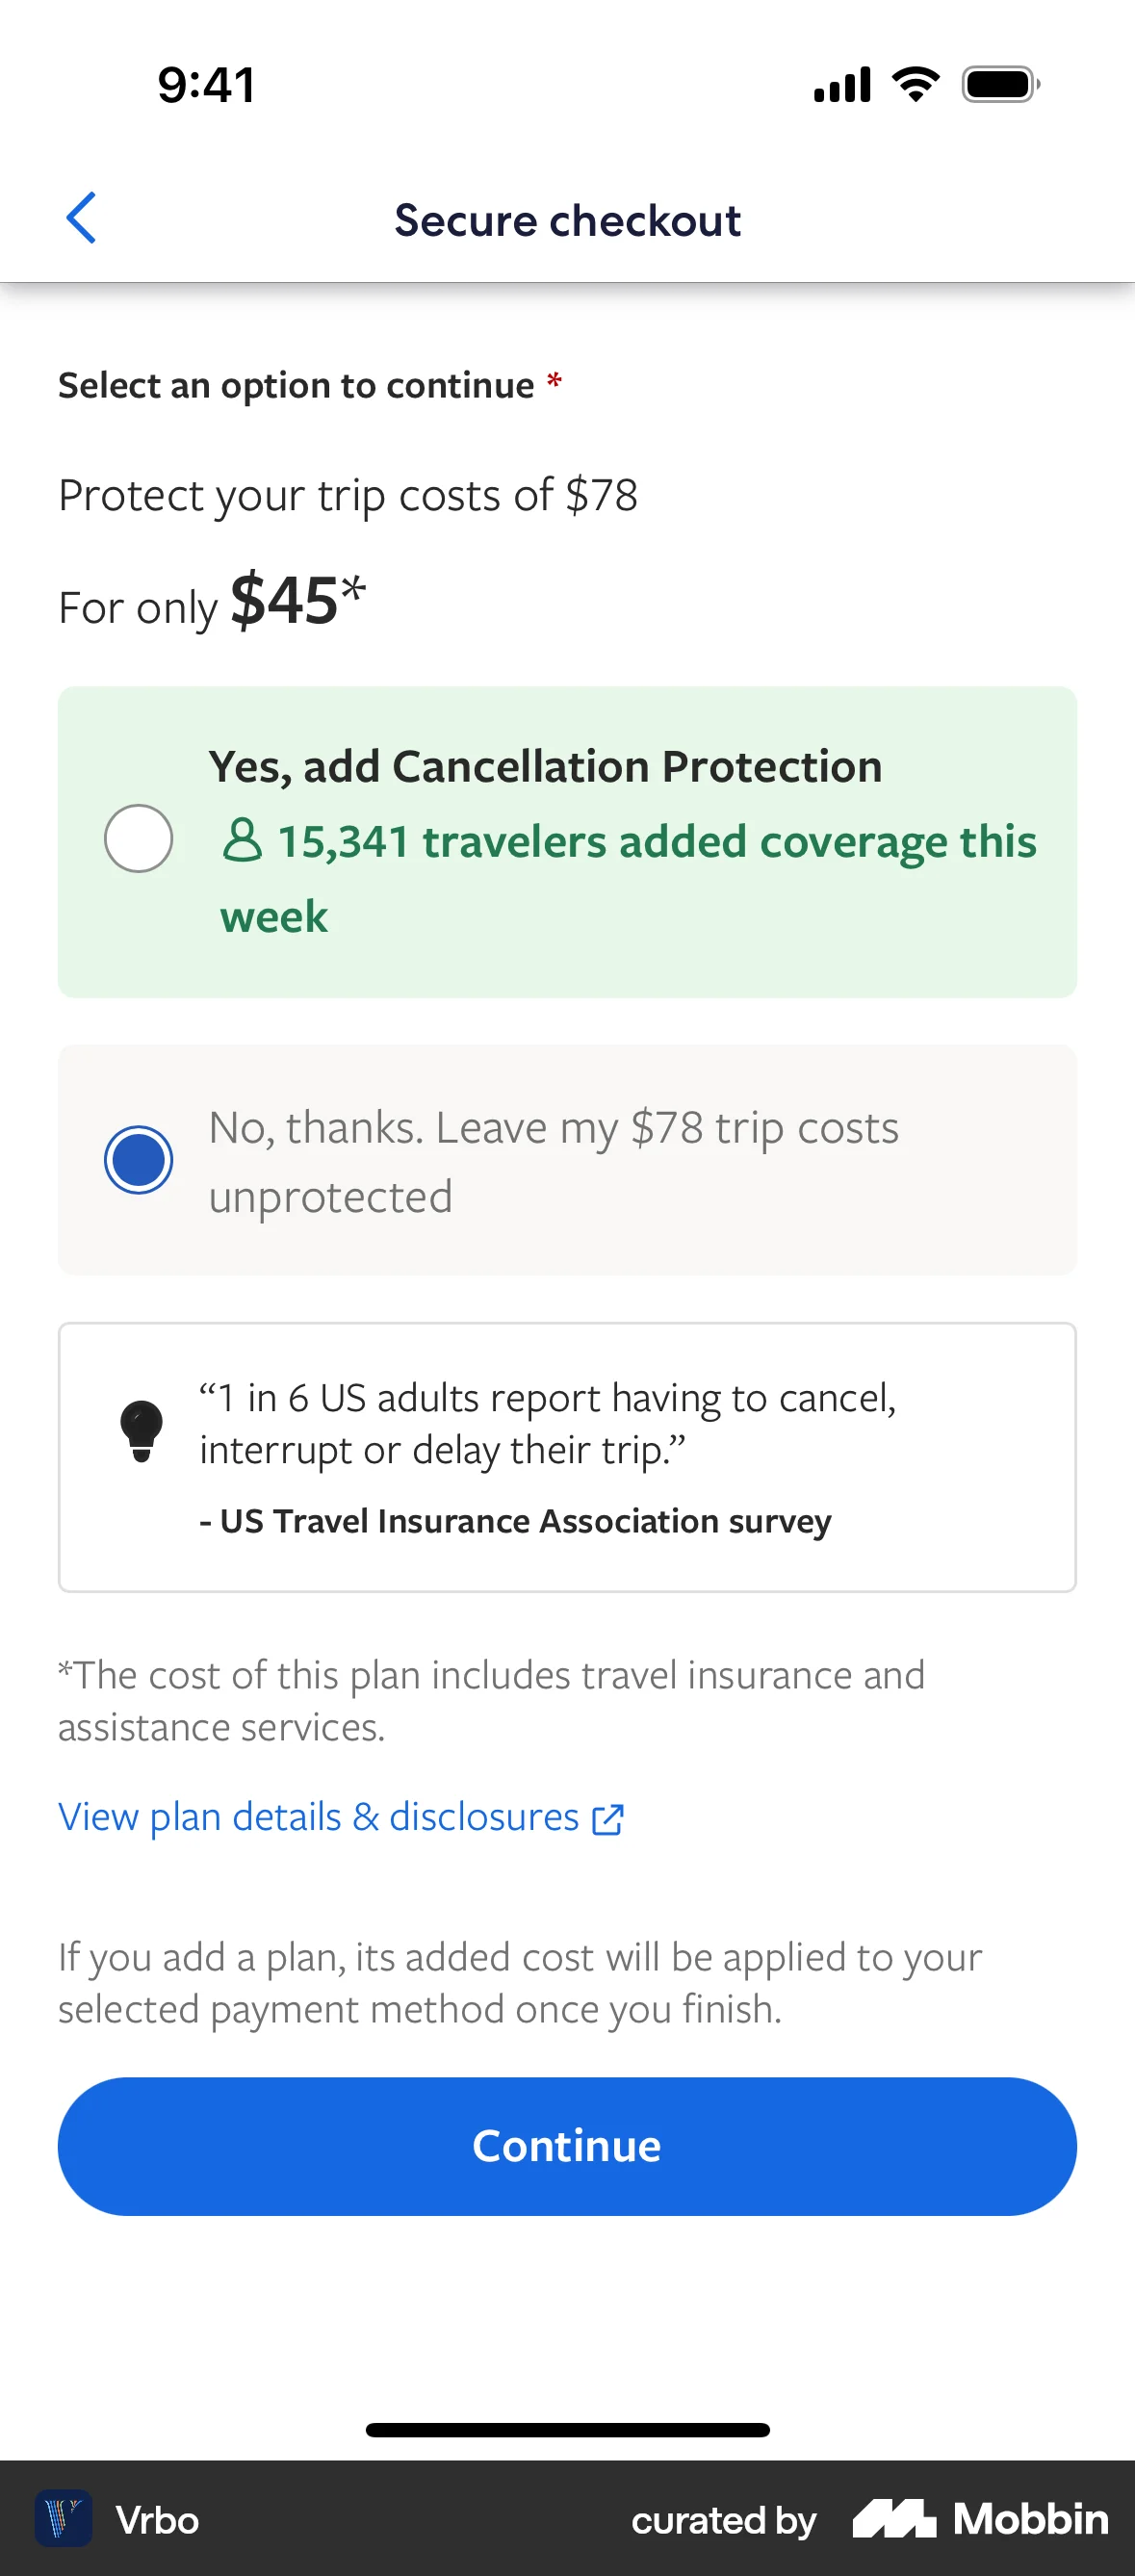
- State risk in pricing and add-on flows as a natural frequency with a denominator and period (“about 3 of every 1,000 phones are reported stolen each year”) instead of a vivid case. Unpacking a hazard into named sub-cases raises its judged probability.
- Treat the cap on “how many times did you…” survey and onboarding questions as part of the measurement. A high recall demand lowers the self-assessment that follows, so the same question with a different cap returns a different answer.
What to avoid
- Making a rare risk vivid to sell protection against it. In the UK this is a banned practice outright: paragraph 14 of Schedule 20 to the Digital Markets, Competition and Consumers Act 2024 prohibits making a materially inaccurate claim about the nature or extent of the risk to the personal security or safety of the consumer, their family or anyone living in their home if they do not buy the product. No likelihood test, no defence of exaggeration.
- Dressing a prevalence claim up in true stories. Section 226 of the same Act treats information that is true but presented in a misleading way as a misleading action, and says a presentation can deceive even where every individual piece of information in it is true — which is precisely what a curated wall of successes is.
- Asking users to recall many instances of something you want them to rate highly. Twelve assertive behaviours produced lower self-ratings than six, and ten solicited criticisms produced higher course ratings than two.
- Planning around an ease-of-retrieval effect without testing it in your own flow. It carries publication bias of up to a third of its size, reverses under non-standard manipulations, and failed to appear in a representative national sample and in a direct replication of the original study.
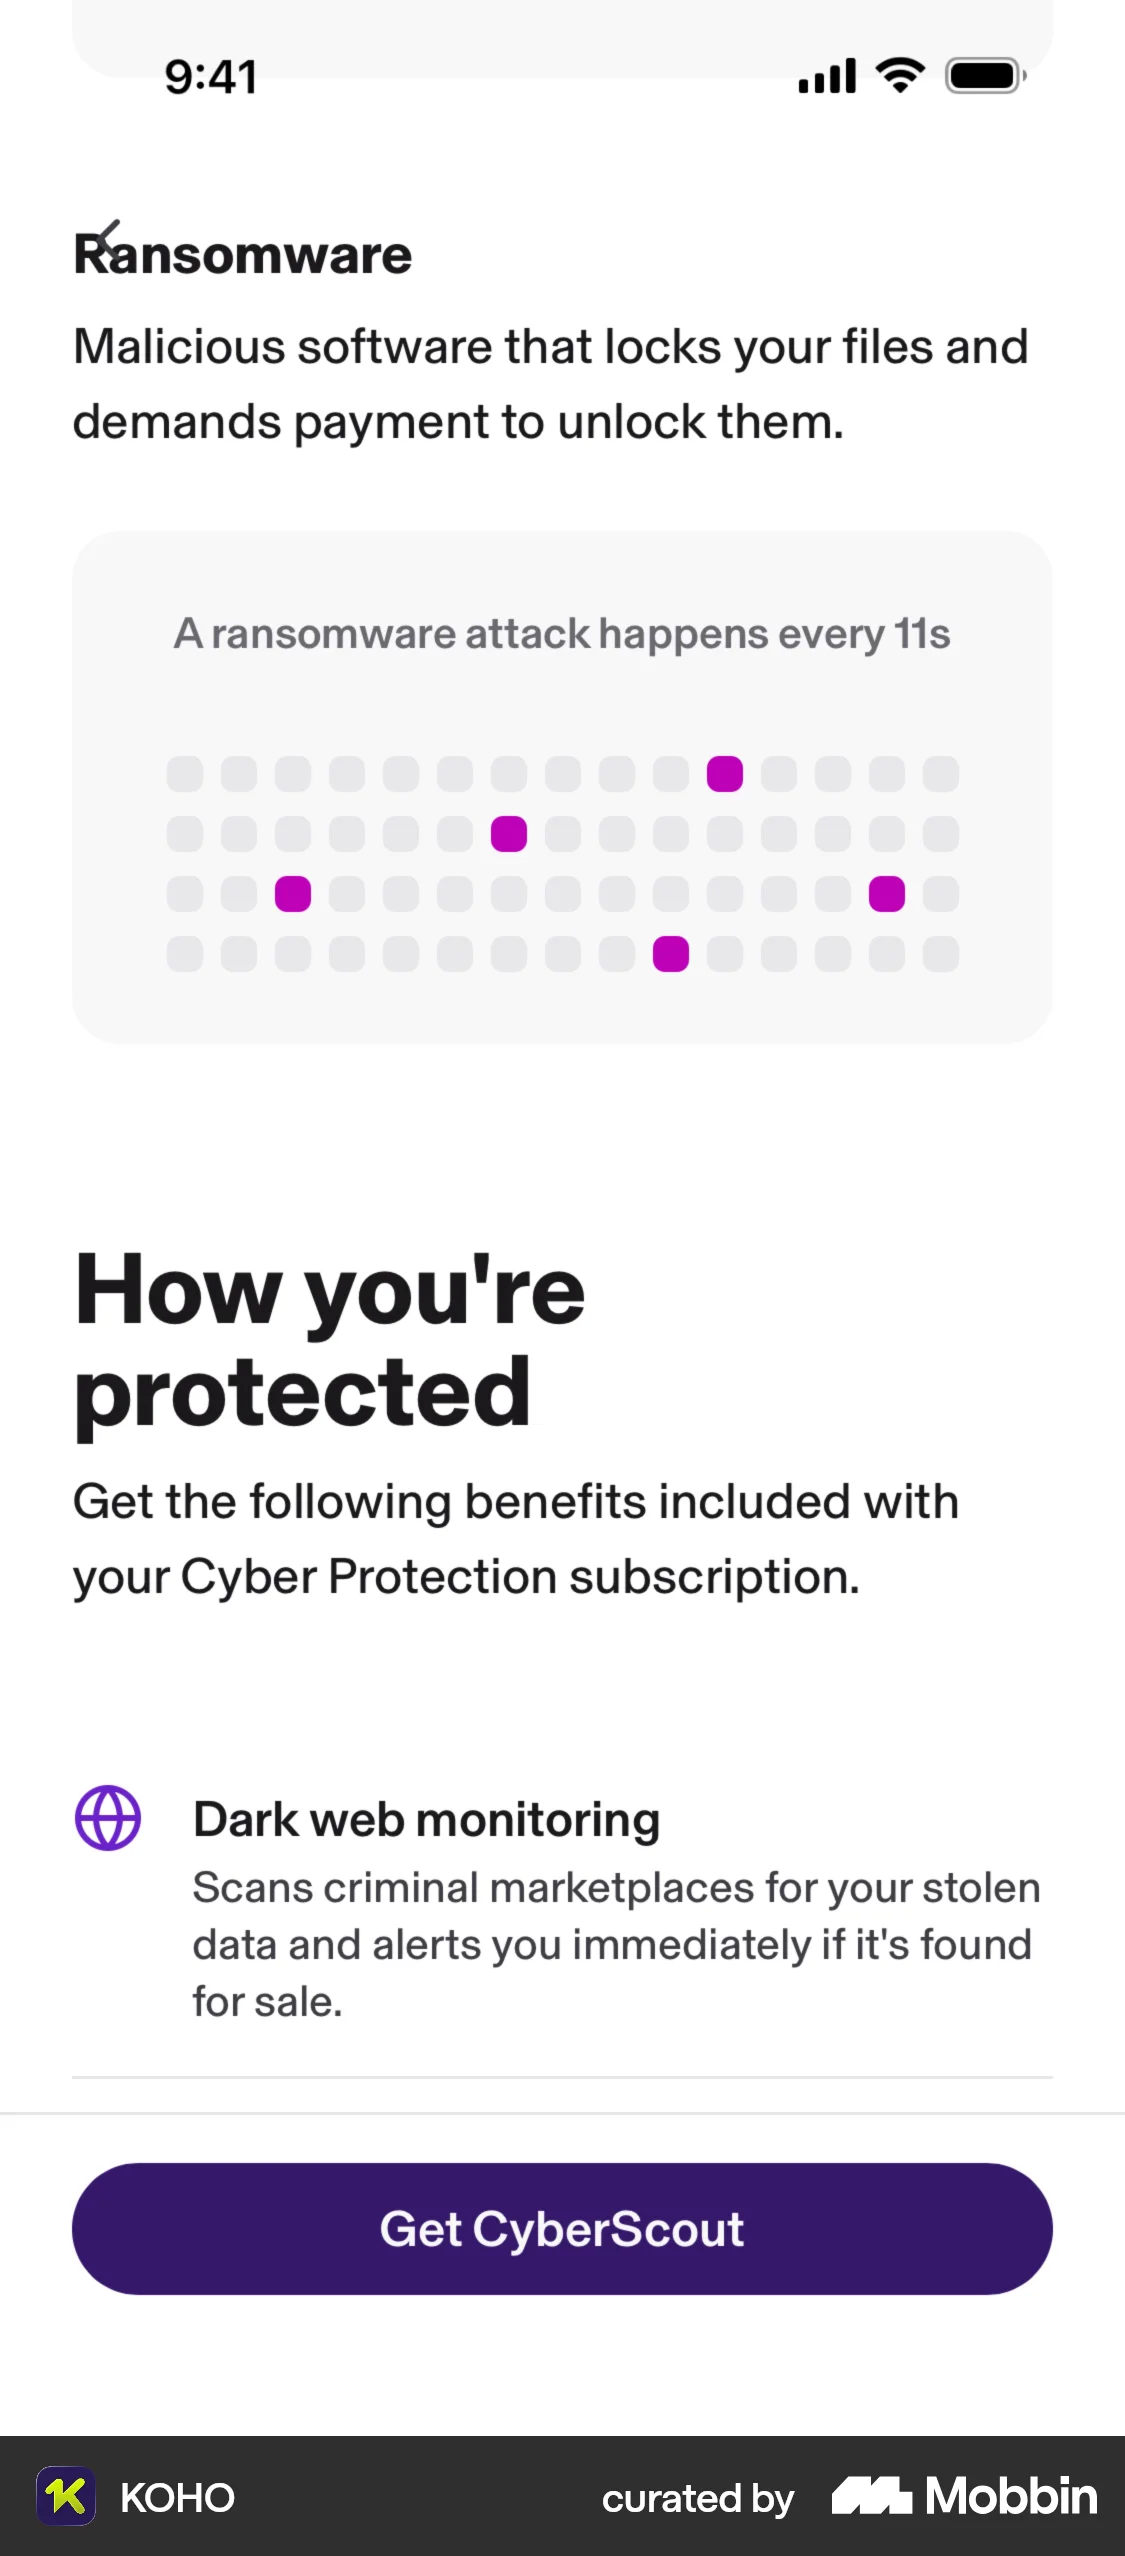
- Leaning on media-style exposure — repeated banners, news-shaped alerts, breach tickers — to shift a risk judgment. In the study that separated channels, media encounters contributed negligibly and personal-network occurrences did the work.
- Fabricating or selectively staging the examples themselves. A case study, review or “customers like you” figure not drawn from real outcomes is a fake prevalence signal, and under Schedule 20 paragraph 13 commissioning or misleadingly publishing reviews is separately banned.
- Showing a vivid loss story next to a buy button with no base rate anywhere on the screen. That is the exact configuration in which anecdotes pulled choices away from the statistically better option.
Real-world examples
Measuring it
- Primary metric: take-up of the thing the examples support — plan selection, add-on attach, flow completion — against a variant carrying the same claim with no exemplars, not against no claim at all.
- Secondary metric: an elicited estimate from users (“out of 100 customers like you, how many achieve this?”) compared with your actual rate. It is the only read on whether you moved perception, and in which direction.
- Backfire metric: completion and drop-off on any prompt asking for reasons, examples or criticisms, split by the cap you set and by the number actually entered. A low produced-to-solicited ratio is the published mediator of the reversal.
- Backfire metric: calibration gap by segment, plus retention of users who converted off an exemplar-heavy screen against those who converted off a base-rate screen. Estimates above your real rate are activation that refunds and support contacts collect on later.
- Backfire metric: for risk-led pricing or protection offers, cancellation and refund rate within the first two billing periods and complaints mentioning pressure or exaggeration.
References
- Tversky & Kahneman (1973). Availability: A Heuristic for Judging Frequency and Probability. Cognitive Psychology.
- Schwarz, Bless, Strack, Klumpp, Rittenauer-Schatka & Simons (1991). Ease of Retrieval as Information: Another Look at the Availability Heuristic. Journal of Personality and Social Psychology.
- Weingarten & Hutchinson (2018). Does Ease Mediate the Ease-of-Retrieval Effect? A Meta-Analysis. Psychological Bulletin.
- Yeager, Krosnick, Visser, Holbrook & Tahk (2019). Moderation of Classic Social Psychological Effects by Demographics in the U.S. Adult Population. Journal of Personality and Social Psychology.
- Groncki, Beaudry & Sauer (2021). Investigating the Ease-of-Retrieval Effect in an Eyewitness Context. Memory.
- Fox (2006). The Availability Heuristic in the Classroom: How Soliciting More Criticism Can Boost Your Course Ratings. Judgment and Decision Making.
- Lichtenstein, Slovic, Fischhoff, Layman & Combs (1978). Judged Frequency of Lethal Events. Journal of Experimental Psychology: Human Learning and Memory.
- Sedlmeier, Hertwig & Gigerenzer (1998). Are Judgments of the Positional Frequencies of Letters Systematically Biased Due to Availability? Journal of Experimental Psychology: Learning, Memory, and Cognition.
- Hertwig, Pachur & Kurzenhäuser (2005). Judgments of Risk Frequencies: Tests of Possible Cognitive Mechanisms. Journal of Experimental Psychology: Learning, Memory, and Cognition.
- Pachur, Hertwig & Steinmann (2012). How Do People Judge Risks: Availability Heuristic, Affect Heuristic, or Both? Journal of Experimental Psychology: Applied.
- Efendić (2021). How Do People Judge Risk? Availability May Upstage Affect in the Construction of Risk Judgments. Risk Analysis.
- Fagerlin, Wang & Ubel (2005). Reducing the Influence of Anecdotal Reasoning on People's Health Care Decisions: Is a Picture Worth a Thousand Statistics? Medical Decision Making.
- Tversky & Koehler (1994). Support Theory: A Nonextensional Representation of Subjective Probability. Psychological Review.
- Gigerenzer & Hoffrage (1995). How to Improve Bayesian Reasoning Without Instruction: Frequency Formats. Psychological Review.
- Digital Markets, Competition and Consumers Act 2024, Schedule 20 (banned practices), paragraph 14.
- Digital Markets, Competition and Consumers Act 2024, section 226 (misleading actions).
For agents
An agent-friendly guide to this principle lives at /agents/availability-heuristic.md.
Our MCP server and skills for all principles are coming soon.
Similar principles
Disclaimer: The theories here are just that — theories. They may not apply universally and should be considered in context. Use your own judgment and consult additional sources when applying these principles.